What happened
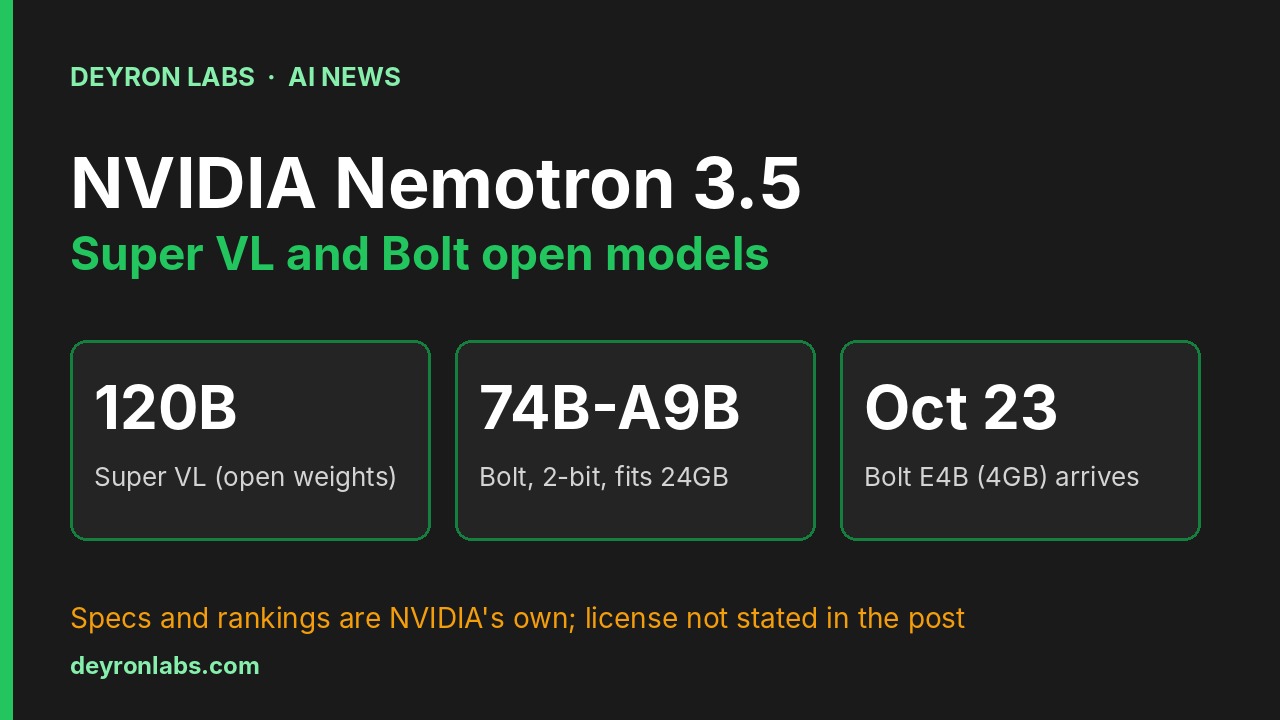
On 15 October 2026, NVIDIA published a blog post introducing three additions to its Nemotron family: Nemotron 3.5 Super VL, Nemotron 3.5 Bolt 74B-A9B 24GB and Nemotron 3.5 Bolt E4B 4GB. NVIDIA says Super VL and Bolt 74B-A9B are available now, and Bolt E4B arrives on 23 October.
Key details
All figures below are NVIDIA’s, taken from its announcement; we have not tested the models and found no independent evaluation yet.
- Super VL: a 120-billion-parameter open vision-language model aimed at always-on enterprise agents. NVIDIA says it reaches accuracy comparable to its largest reasoning model at about one-fifth of the parameters and is 5x faster than the next best open agentic model in its class. The post says it ships with open weights, open datasets and training recipes, after about 26 trillion tokens of pretraining and continued pretraining and post-training on roughly 3.8 million samples plus reinforcement learning. The model name suggests about 12B active parameters; the post does not state this.
- Bolt 74B-A9B 24GB: a 74-billion-parameter model with about 9 billion active parameters (from the model name), using native 2-bit quantization to fit in 24GB of memory. NVIDIA says it ranks first among open models in its class on PinchBench and second on BrowseComp, without giving numeric scores. It lists support for llama.cpp, Ollama, LM Studio, Unsloth and vLLM.
- Bolt E4B 4GB: a small model for conversational agents such as local voice assistants, arriving 23 October. Parameter count and benchmarks were not given.
- Where to get them: Hugging Face, OpenRouter, ModelScope and NVIDIA NIM for Super VL; Hugging Face for Bolt 74B-A9B.
- Not stated in the post: the license, numeric benchmark scores, and the hardware needed beyond the 24GB figure for Bolt.
Why it matters
The practical point is Bolt 74B-A9B: a model of that size squeezed into 24GB targets a single high-end consumer GPU, which would put a large mixture-of-experts model within reach of many hobbyists and small teams. Whether 2-bit quantization keeps quality high enough is the open question, and NVIDIA’s rankings come without scores.
Before building on any of these models, check the license on the Hugging Face model card, since the announcement does not name one, and wait for independent benchmarks.
Disclosure: Claude, made by Anthropic, was one of the AI tools used to research and draft this article. Claims and specifications are NVIDIA’s own.