What happened
NVIDIA published a roundup of local-AI announcements on 21 October 2026 from GTC Berlin. It says it is highlighting “secure, local systems across RTX Spark, DGX Spark and DGX Station” for coding, engineering, robotics and AI factory development.
Key details
All figures below are NVIDIA’s, taken from its post.
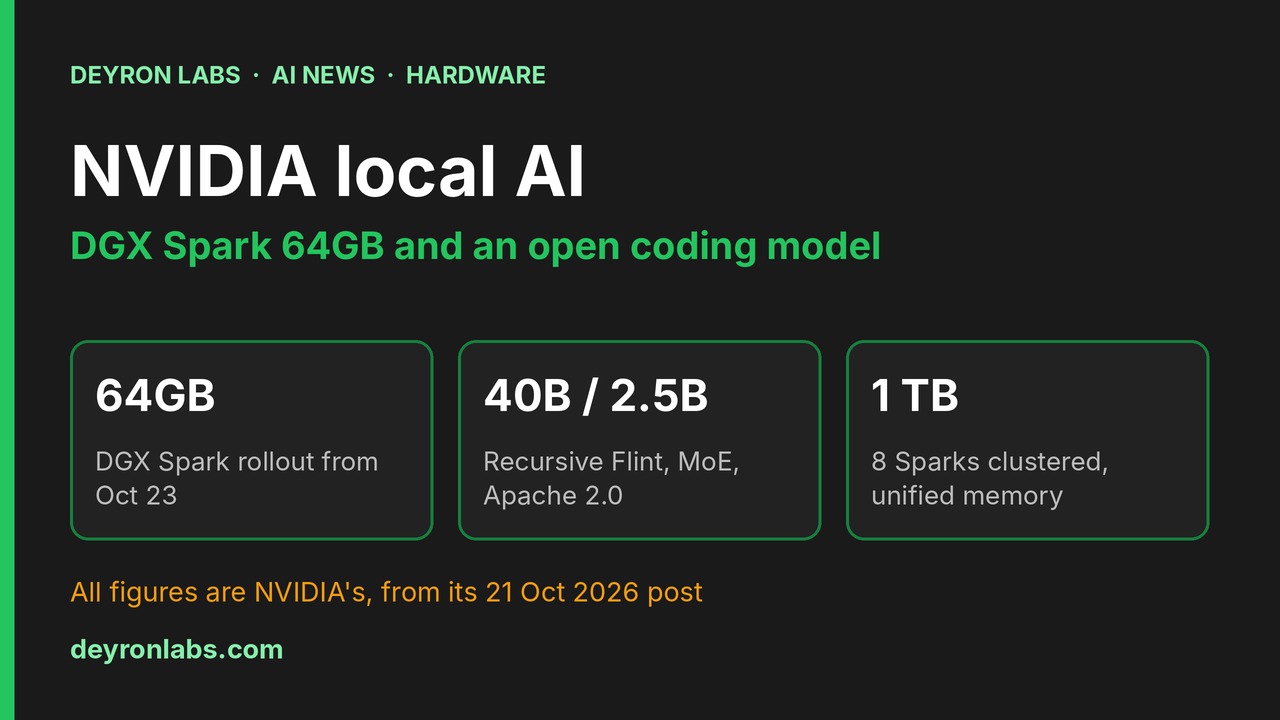
- DGX Spark 64GB: systems start rolling out from partners on Friday 23 October. NVIDIA lists Nemotron 3.5 Bolt 74B (24GB), Qwen3.8 27B and Gemma 4 26B-A4B among the models they run. Up to eight units can be clustered manually, which NVIDIA says gives 1TB of unified memory. A Model Launcher for NVIDIA Sync is due “later this month”.
- RTX Spark: NVIDIA describes it as offering up to 128GB of unified memory and 1 petaflop of AI compute, available since 16 October in laptops from ASUS, Dell Technologies, HP, Lenovo, Microsoft and MSI, with Acer “coming soon”.
- DGX Station: 748GB of coherent memory and up to 20 petaflops of AI performance. NVIDIA announced seven new management integrations, such as Microsoft Intune and Splunk by Cisco. DGX Station for Windows is expected in December.
- Recursive Flint: a new local coding model from Recursive Superintelligence. NVIDIA describes a 40-billion-parameter mixture-of-experts model with 2.5 billion active parameters, open weights under Apache 2.0, and “over 220 tokens per second on a 64GB RTX Spark”. NVIDIA says optimized kernels raised generation speed on RTX Spark by 55% without changing the weights.
- Day-zero model support: NVIDIA lists new Nemotron, GLM, DeepSeek, Qwen, MiniMax and FLUX.3 models, including Black Forest Labs’ FLUX.3 Klein (5.6 billion parameters, 8GB of VRAM) and Nemotron Bolt E4B, which NVIDIA says needs as little as 4GB of memory and releases on 23 October.
- Inference speedups: NVIDIA reports up to 1.4x for Qwen 3.8 Flash Next in llama.cpp on RTX PRO 6000 Blackwell, up to 1.3x for Qwen3.8 27B in vLLM on DGX Spark, and up to 1.2x for GLM 5.3 Flash on DGX Station.
Why it matters
For people running models on their own hardware, the practical news is a cheaper-memory DGX Spark option, an easier way to pool several units, and a permissively licensed coding model sized for them. The speed and memory numbers come from NVIDIA, were not independently tested, and compare against NVIDIA’s own baselines, so real results will depend on the model, quantization and software setup.
Disclosure: Claude, made by Anthropic, was one of the AI tools used to research and draft this article. Details come from NVIDIA’s post of 21 October 2026, read on 22 October 2026.
Sources
- Bringing the Spark to Europe: Local Intelligence Powers Next Wave of Agents Primary source , NVIDIA